What does improving an AI video analytics model actually look like?

AI models don’t arrive finished.
Not because they were unfinished when they were deployed, but because the world they need to understand doesn’t stand still.
A video analytics model has to recognise the things that matter across an enormous range of conditions: different cameras, different image quality, different scenes, seasons, lighting, weather and distances.
You can’t show a model every version of the world before it goes into production.
So the job is to build something that generalises well to what we know, deploy it, and then keep learning from what happens in the field.
Here’s roughly what that process looks like for us.
We look for where the balance can improve.
A model might perform extremely well across most scenes but be less confident under a particular combination of conditions. It might be a new camera type producing an image differently, a seasonal change in the way a scene looks, or something in the environment is introduced that might look surprisingly similar to an object we want to detect.
These aren’t simply “mistakes” to correct. They help us understand how the model is interpreting the visual world.
Then we investigate why.
The important question isn’t just what happened?
It’s why did the model respond that way?
Sometimes the answer is in the data. Sometimes it is the way the model has learned to prioritise certain visual features. Sometimes improving performance in one area has subtly changed the balance somewhere else.
That investigation tells us what needs to change.
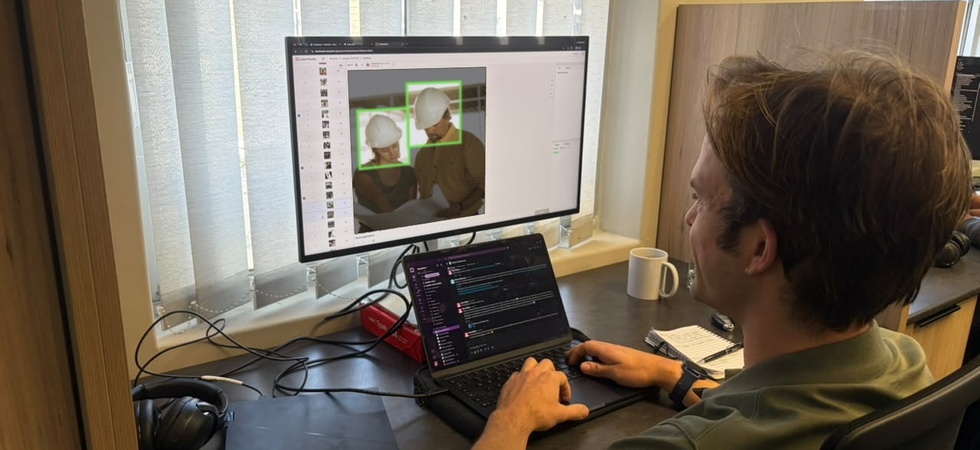
We give the model better examples of the distinction we want it to understand.
That may mean finding more representative data from a particular type of camera, environment or condition.
But the aim isn’t simply to keep adding more data.
It is to help the model understand the underlying difference more clearly: what should increase its confidence, what should reduce it, and which visual similarities it needs to learn to ignore.
Then we test whether the change generalises.
Improving one difficult scenario is only useful if we haven’t made the model worse somewhere else.
So changes are tested against footage and environments the model hasn’t trained on, across a much wider range of conditions than the original case.
The goal is balance.
More confidence in the objects that matter and less attention paid to things that only look confusingly similar. This produces consistent performance across a constantly changing camera estate.
Then the process starts again.
New cameras appear. Image quality changes. Sites change. Seasons change. New environments introduce things we didn’t expect to see.
And sometimes a model encounters something in production that teaches us something genuinely unexpected about how it has learned to interpret a scene.
That’s one of the most interesting parts of building AI for real-world surveillance.
The model we deploy today is not the end point. It is the result of everything we have learned so far and the starting point for what we learn next.
Better models mean operators receive clearer, more reliable information while they remain responsible for the decision and response.
If you run a control room, which difficult scenes or conditions would you most like video analytics to handle more confidently?
Those difficult real-world cases are often where some of the most useful learning begins.
Related Articles